UCL Match Forecasting
Forecast Champions League match outcomes using football statistics and market odds, with chronological evaluation and recorded pre-match predictions.
- Python
- pandas
- scikit-learn
- Statistical Modeling
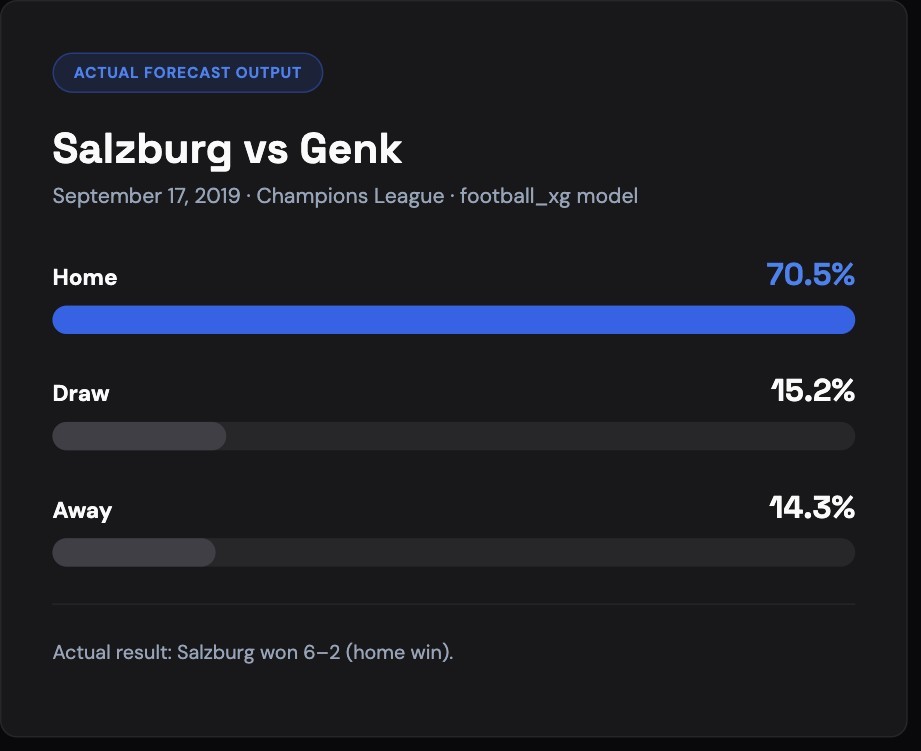
Predict probabilities, not just winners
The project estimates home-win, draw, and away-win probabilities for regulation-time Champions League matches, comparing football-based models against market-odds and base-rate benchmarks rather than just picking a winner.
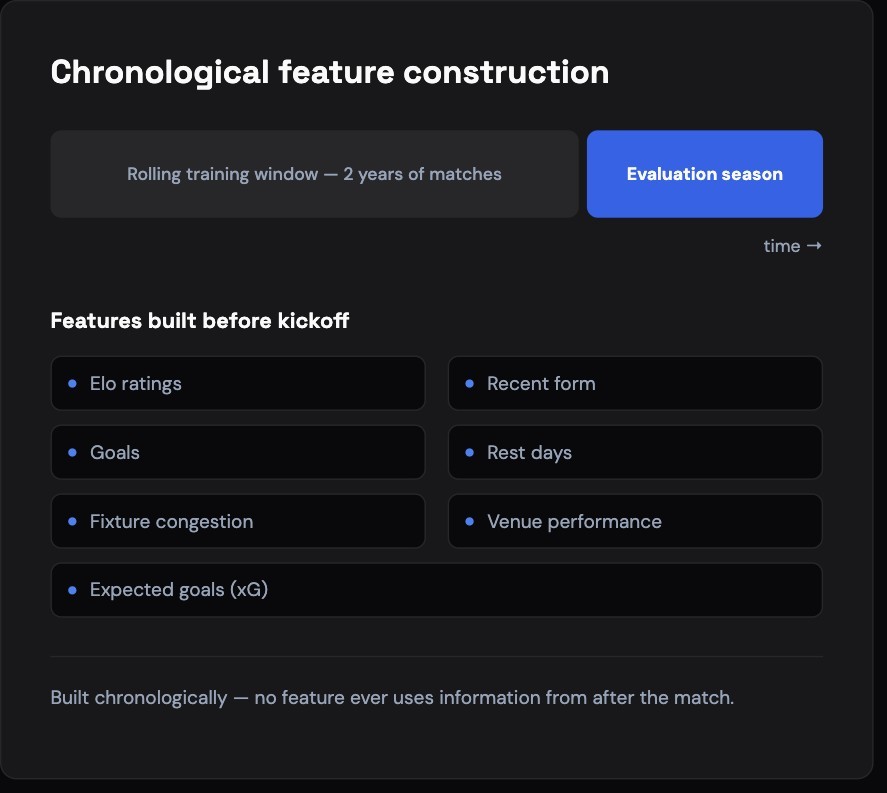
Build features available before kickoff
Each match is described using only information available before kickoff — Elo ratings, recent form, goals, rest days, fixture congestion, venue performance, and expected goals (xG) — built chronologically so no feature ever leaks information from after the match. Models retrain on a rolling two-year window ahead of each evaluation season.
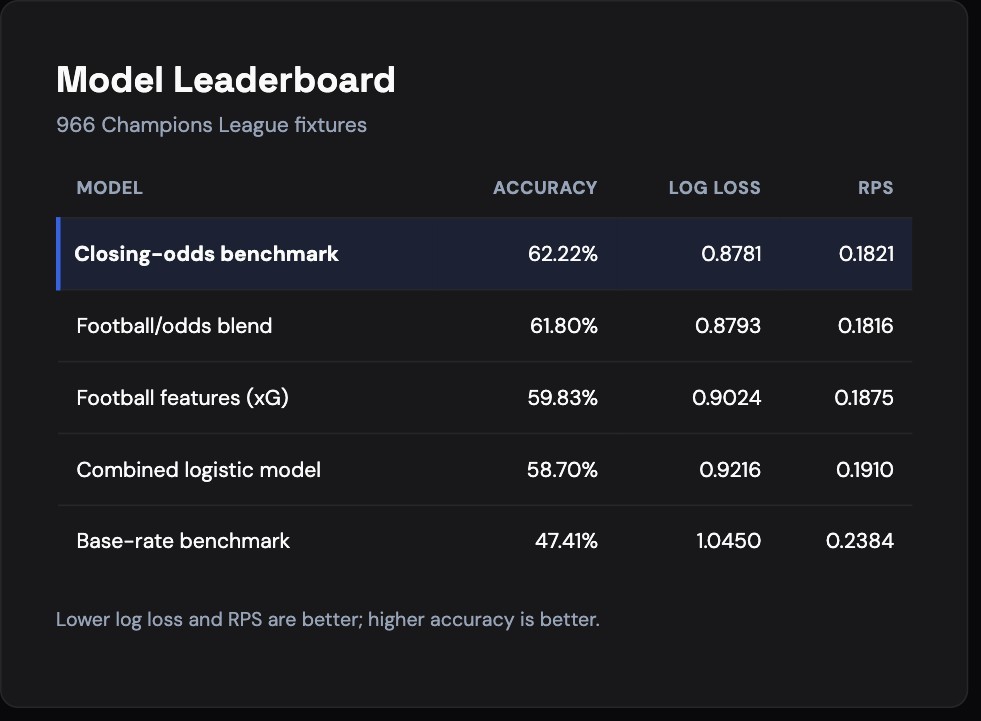
Compare against meaningful baselines
Five models were compared on the same 966 UCL fixtures, evaluated on accuracy, log loss, and ranked probability score rather than accuracy alone. The closing-odds benchmark led at 62.22% accuracy, with a football/odds blend close behind at 61.80%. Football features alone (with xG) reached 59.83%, and a combined logistic model scored 58.70%, both comfortably ahead of the 47.41% base rate — a sign the engineered features carry real signal, even though closing-market odds, gathered minutes before kickoff, remain a tough benchmark to beat. These are retrospective results on previously-inspected development seasons, not a held-out test of future accuracy.
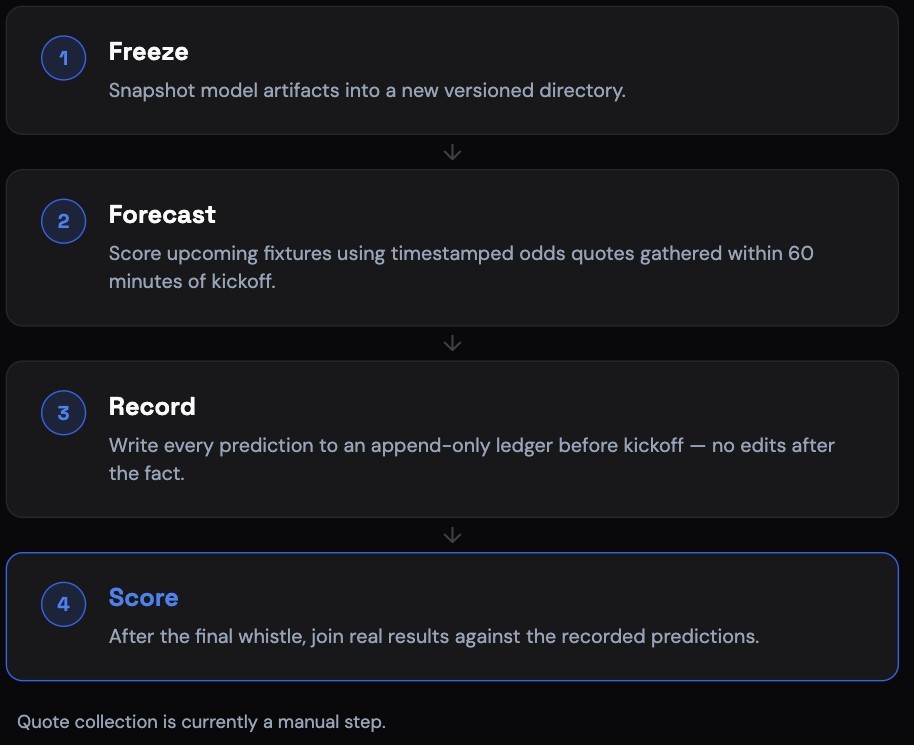
Record predictions before results exist
A forecasting workflow freezes model artifacts, checks quote freshness and kickoff timing, and records each prediction in an append-only SQLite ledger before the match is played — so it can be scored later without any chance of hindsight leaking in. Quote collection is currently a manual step; automating live tracking is still on the roadmap.